Extracting data from lab reports
Clinical laboratories print results from their laboratory information systems, each with its own letterhead, panel layout and units. Insurers, clinical research teams and care coordinators receive reports from many labs every day, as PDFs from lab portals, faxed pages or patient uploads.
Clinical review needs each test's name, result, unit and reference range, with the patient's age and sex that set the range. Those values feed an electronic health record or a claims review system, which compares each result with its range.
What makes lab reports hard
Flags in their own column
An H or L between the test name and the value marks an abnormal result, often with the whole row set in bold.
Ranges written as text
Reference ranges print as text such as 13 - 17 or < 2, and each one holds a low and a high bound.
Units that vary by region
Platelet counts print in lakhs per cubic millimeter at labs in India and in thousands per microliter at labs in the US.
Parse, extract, verify
Parse
Parse turns the document into reading-order Markdown and a hierarchy of blocks (text, tables, figures), and grounds each block to its exact location on the page.
Extract
You define the fields in a JSON schema, and Extract returns their values in a consistent, structured format, each linked back to where it appears in the Markdown.
Verify
Each value links back to where it appears, down to the character range in the Markdown, and the page and bounding box in the source document, so every result can be verified.
One lab report, end to end
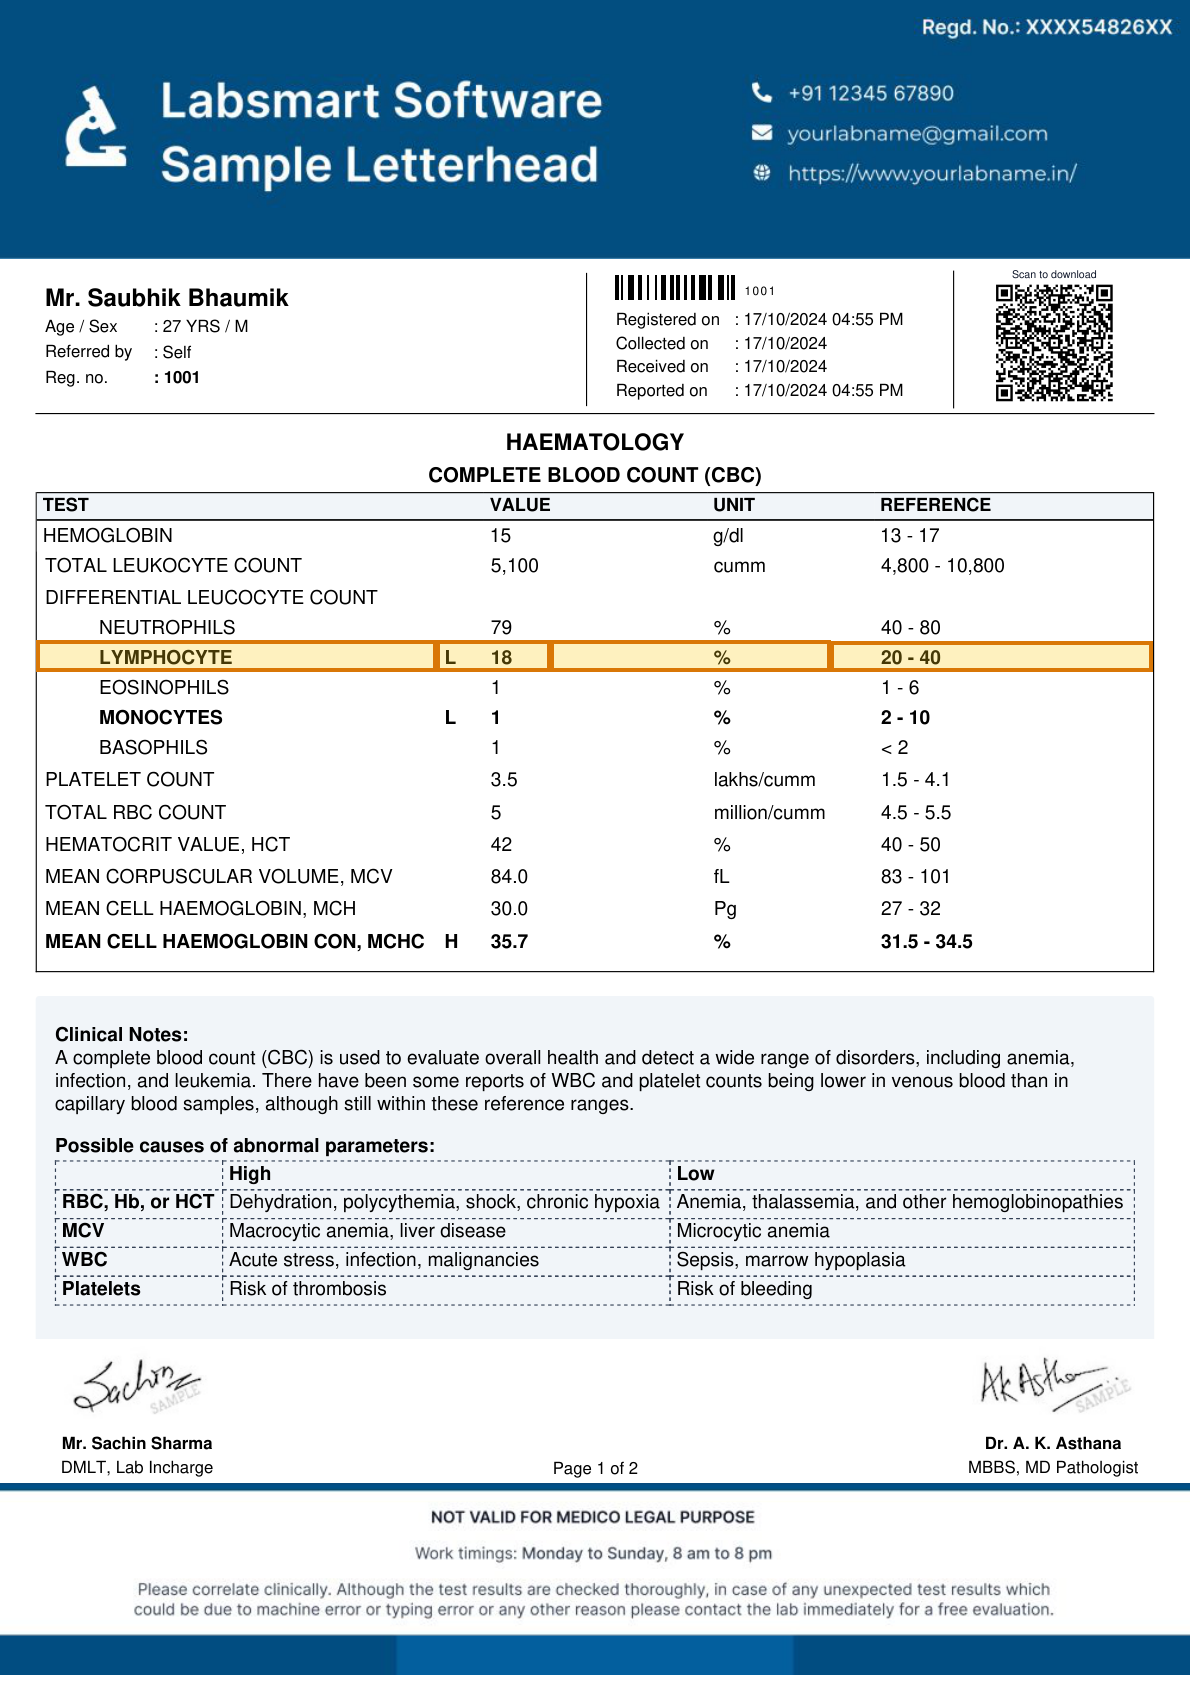
About this document: A complete blood count report from LabSmart, a laboratory information system vendor, printed on its sample letterhead to show the software's output. Two portrait pages: a patient and sample header, a 13-row hematology results table, a clinical notes panel and signature blocks. Page 1 is featured. Every patient detail is the vendor's placeholder.
Processing objective: The objective is to read one result that falls outside its range. The lymphocyte count is a percentage, flagged low on the report, and sits below the lower bound of its reference range. Each of those values grounds to its own cell in that row.
Demonstration fields: Test, Result, Unit, Reference range low
The document
2 of 2 pages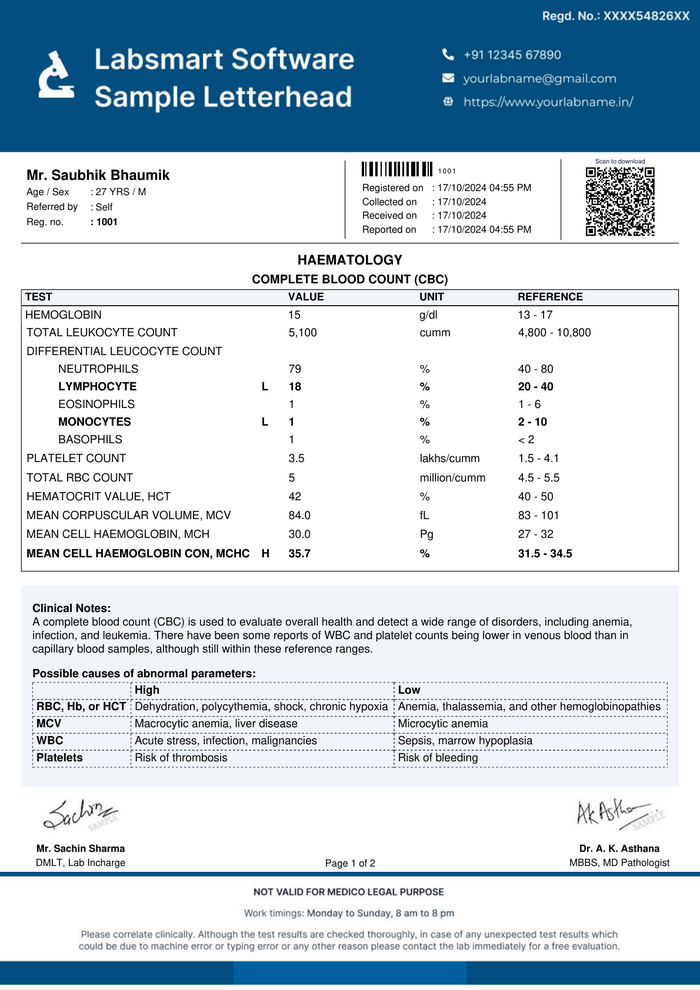 Page 1shown below
 Page 2
Where each value came from
test_results[3].test_name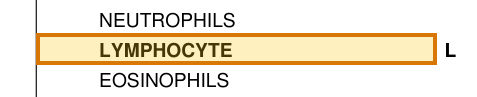
{
  "value": "LYMPHOCYTE",
  "page": 1,
  "range": {
    "end": 818,
    "start": 808
  },
  "box": {
    "xmin": 0.03042,
    "ymin": 0.3805,
    "xmax": 0.36666,
    "ymax": 0.39854
  }
}test_results[3].result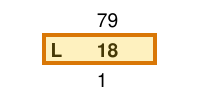
{
  "value": "18",
  "page": 1,
  "range": {
    "end": 831,
    "start": 827
  },
  "box": {
    "xmin": 0.36654,
    "ymin": 0.38058,
    "xmax": 0.46241,
    "ymax": 0.39856
  }
}test_results[3].unit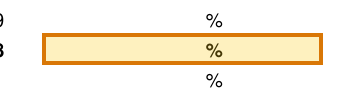
{
  "value": "%",
  "page": 1,
  "range": {
    "end": 841,
    "start": 840
  },
  "box": {
    "xmin": 0.46236,
    "ymin": 0.3806,
    "xmax": 0.69816,
    "ymax": 0.39862
  }
}test_results[3].reference_values[0].reference_low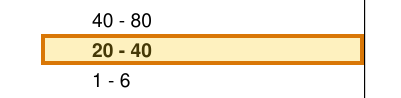
{
  "value": 20,
  "page": 1,
  "range": {
    "end": 857,
    "start": 850
  },
  "box": {
    "xmin": 0.69812,
    "ymin": 0.38066,
    "xmax": 0.96879,
    "ymax": 0.39868
  }
}
How to try it yourself
Everything on this page is reproducible. The sample, its schema, and the Parse and Extract API outputs are published. You can repeat the same two calls from whichever surface you already build on.
- Claude Skilldescribe the job; the agent writes it
- CLIno code at all
- MCPexpose ADE docs as an agent tool
- REST APIany language
- Pythonlandingai-ade
- TypeScriptlandingai-ade
Documents into data
Accurate
The best accuracy on the difficult documents other tools get wrong, such as messy scans, complicated tables, checkboxes and handwriting.
Auditable
Every answer cites its sources. Values come back with an audit trail (page, bounding box, character range) so a human can review them.
Agentic
Applies multi-step reasoning, and plans before it acts. Handles documents it has never seen before and adapts to variations.
API-first
Composable APIs that drop into any tech stack and can be called from anywhere. Easy to build on and embed in your pipelines and products.
Affordable
Cost-competitive rates with complete price transparency. Spend controls before you run, and every job reports its exact cost.
Enterprise-grade
Built for production and scale from day one. Fully observable and monitored, running securely in our cloud or yours.
Built for high-volume, high-throughput production
- Zero data retention
- Priority rate limits
- Enhanced support
- VPC and on-prem deployment
Available on Team and Enterprise plans.