Extracting data from credit reports
Three bureaus supply the data behind US consumer credit reports, and every lender, broker and consumer service renders it into its own layout. A mortgage or auto lender pulls one for every application. A large originator sees thousands a month, arriving as web pages printed to PDF.
An underwriter needs the score, the open balances, the monthly payments and the count of accounts in good standing. An automated underwriting system folds those into a debt-to-income ratio and a decision the lender must be able to explain afterwards.
What makes credit reports hard
A dashboard printed to paper
Headline figures are big-number tiles and the score is a gauge graphic, so the layout is a web page frozen onto a page.
Every account repeats one shape
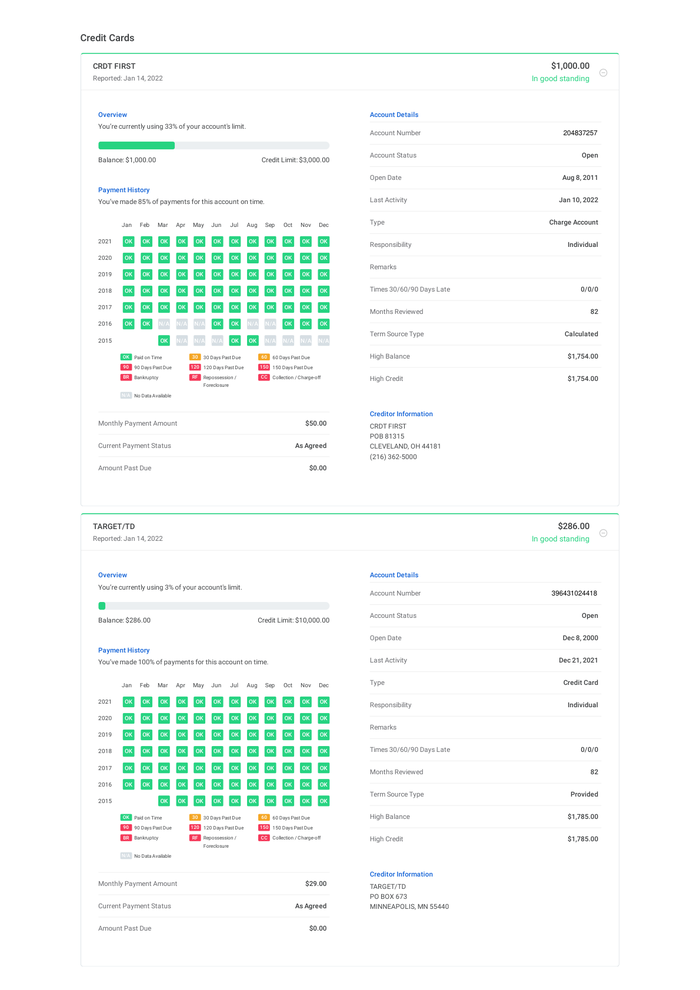
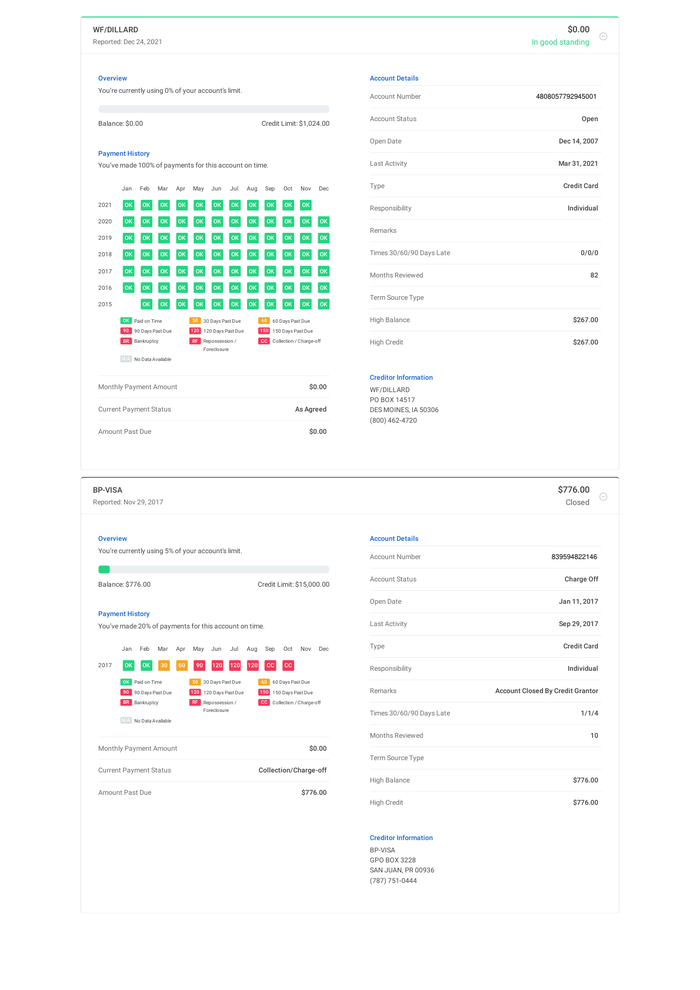
Each tradeline prints the same dozen-odd fields in its own card, and an active file repeats that card across page after page.
Payment history is a color grid
Two years of on-time and late marks sit in a month-by-month grid, where the status of each month is carried by a color.
Parse, extract, verify
Parse
Parse turns the document into reading-order Markdown and a hierarchy of blocks (text, tables, figures), and grounds each block to its exact location on the page.
Extract
You define the fields in a JSON schema, and Extract returns their values in a consistent, structured format, each linked back to where it appears in the Markdown.
Verify
Each value links back to where it appears, down to the character range in the Markdown, and the page and bounding box in the source document, so every result can be verified.
One credit report, end to end
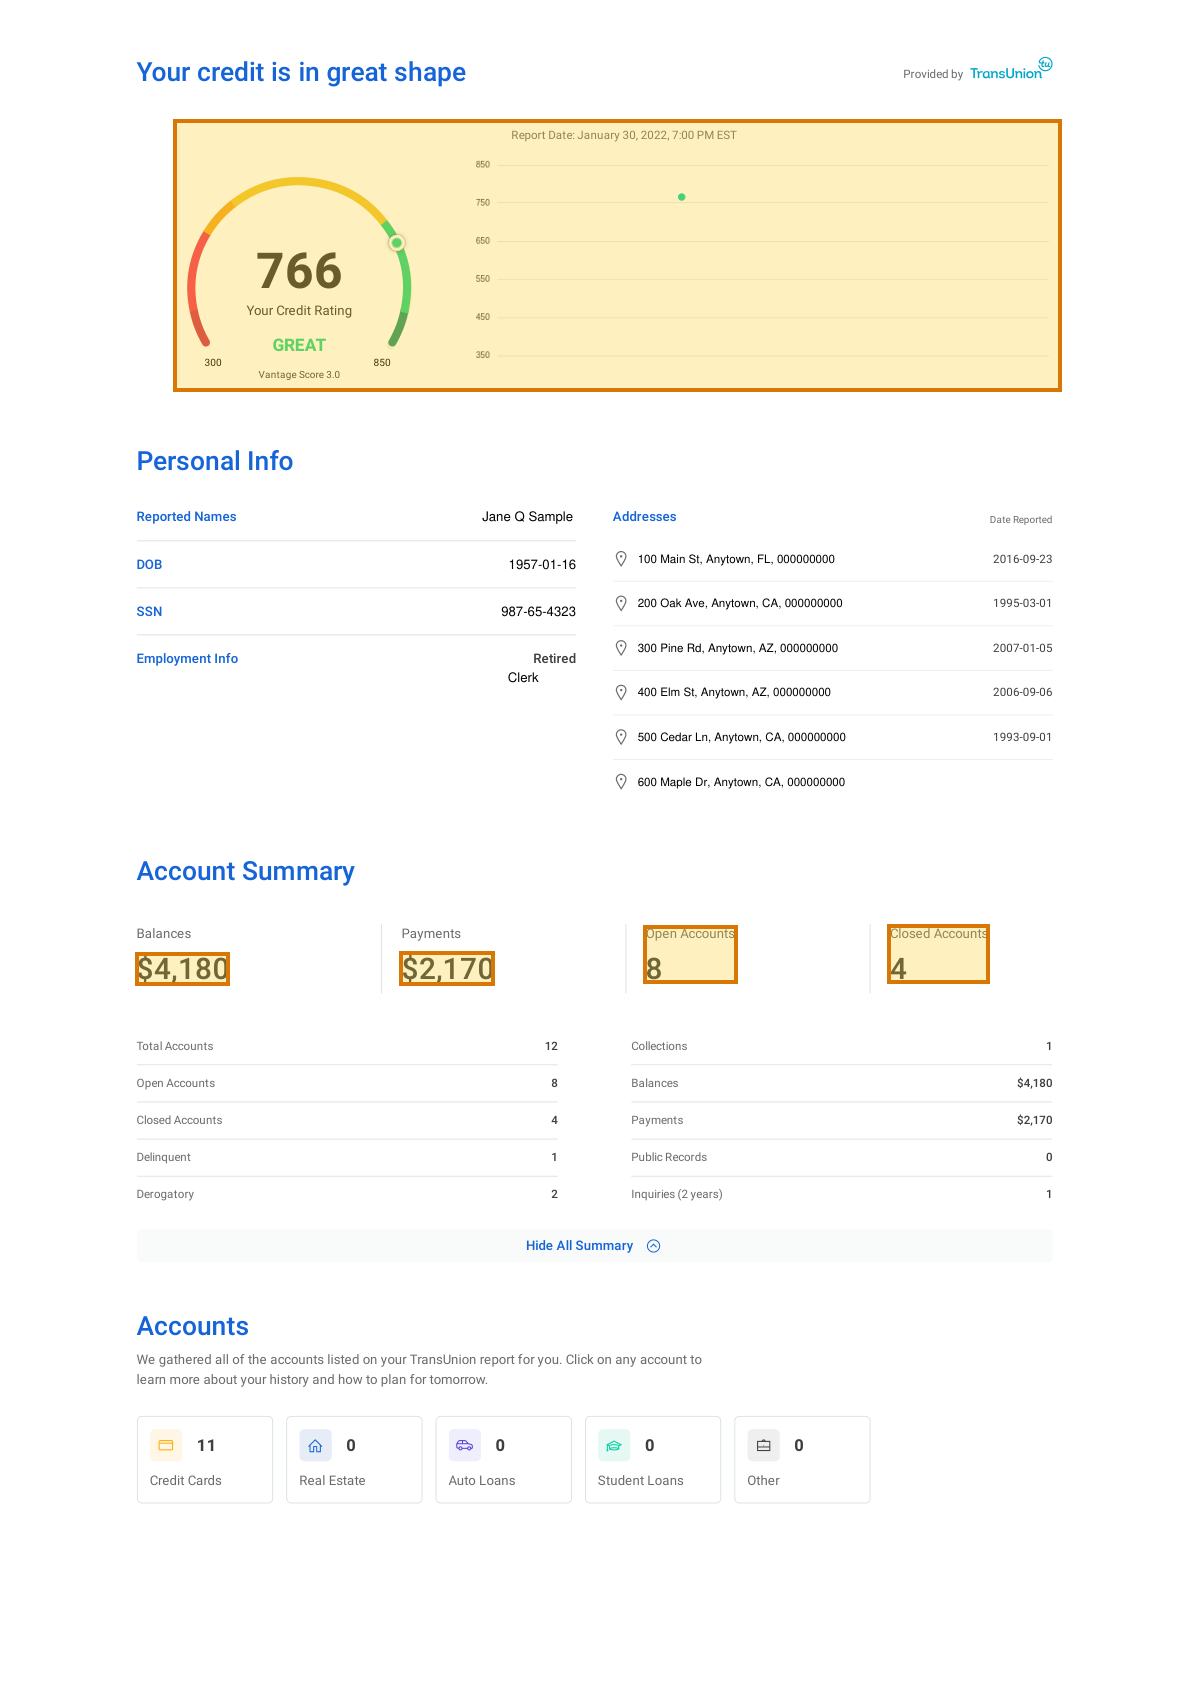
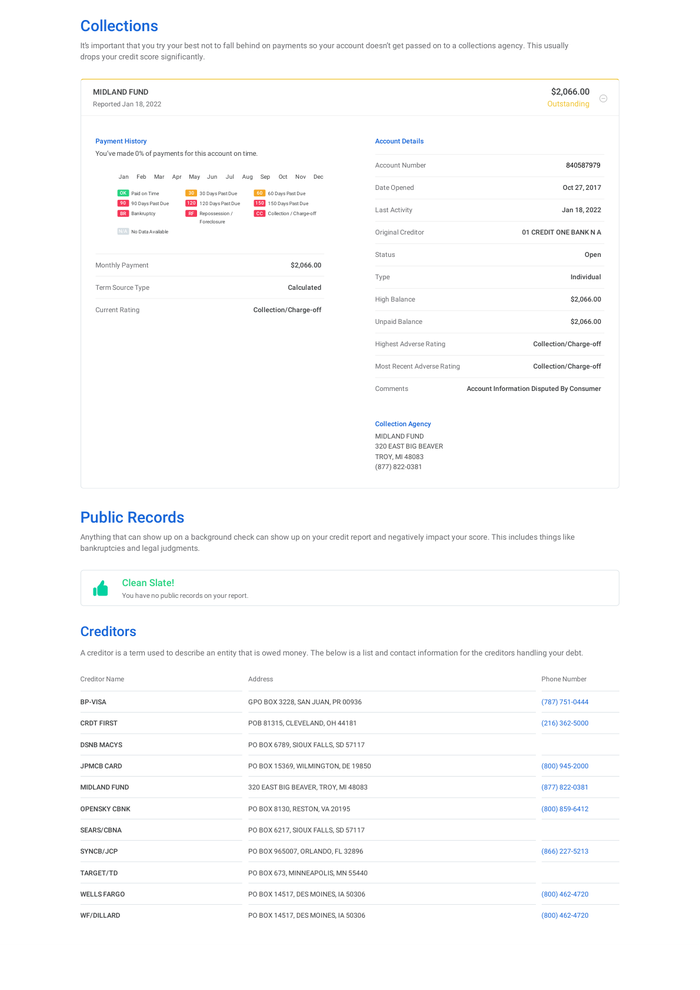
About this document: A consumer credit report built on TransUnion data, rendered from a web page to PDF. Eight portrait pages: a score gauge and summary tiles, then eleven credit card and charge accounts, each a card with a 24-month payment grid, a collection, public records and a creditor directory. Page 1 is featured. Every identifying detail was replaced before publication.
Processing objective: The objective is to lift what an underwriter reads first: the score, and the account summary tiles beneath it. The score is drawn as a gauge, so it is a figure on a page where the four tiles are printed text.
Demonstration fields: Credit score, Total balances, Monthly payments, Open accounts, Closed accounts
The document
4 of 8 pages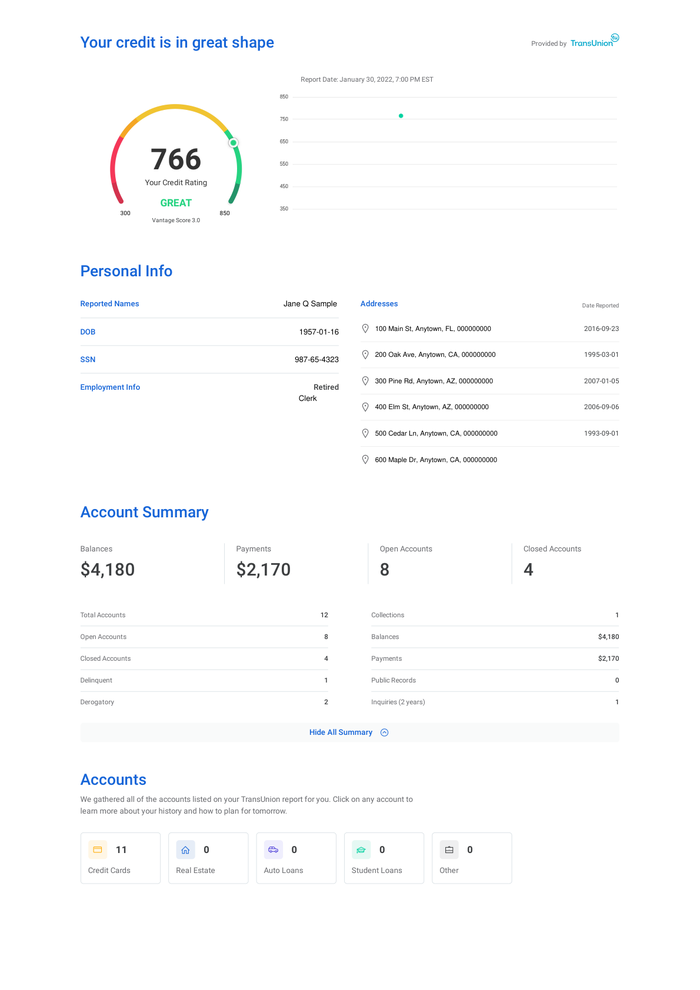 Page 1shown below
 Page 2
 Page 5
 Page 8
Where each value came from
credit_score.score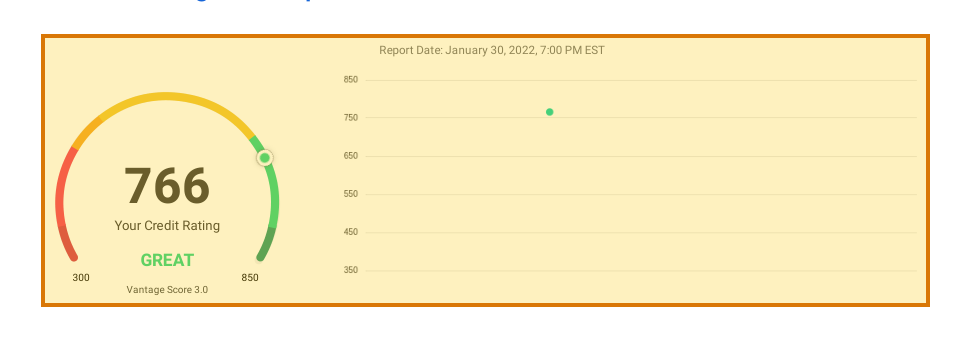
{
  "value": 766,
  "page": 1,
  "range": {
    "end": 761,
    "start": 755
  },
  "box": {
    "xmin": 0.14594,
    "ymin": 0.07075,
    "xmax": 0.8917,
    "ymax": 0.23227
  }
}account_summary.total_balances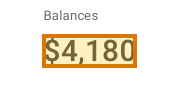
{
  "value": 4180,
  "page": 1,
  "range": {
    "end": 1834,
    "start": 1827
  },
  "box": {
    "xmin": 0.11363,
    "ymin": 0.56545,
    "xmax": 0.19316,
    "ymax": 0.58522
  }
}account_summary.total_monthly_payments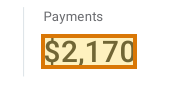
{
  "value": 2170,
  "page": 1,
  "range": {
    "end": 1851,
    "start": 1845
  },
  "box": {
    "xmin": 0.33613,
    "ymin": 0.565,
    "xmax": 0.41557,
    "ymax": 0.58528
  }
}account_summary.open_accounts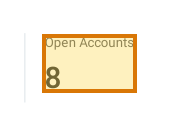
{
  "value": 8,
  "page": 1,
  "range": {
    "end": 1870,
    "start": 1853
  },
  "box": {
    "xmin": 0.5407,
    "ymin": 0.54932,
    "xmax": 0.61957,
    "ymax": 0.58377
  }
}account_summary.closed_accounts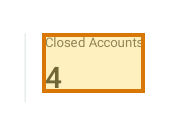
{
  "value": 4,
  "page": 1,
  "range": {
    "end": 1890,
    "start": 1871
  },
  "box": {
    "xmin": 0.74542,
    "ymin": 0.54923,
    "xmax": 0.83178,
    "ymax": 0.58401
  }
}
How to try it yourself
Everything on this page is reproducible. The sample, its schema, and the Parse and Extract API outputs are published. You can repeat the same two calls from whichever surface you already build on.
- Claude Skilldescribe the job; the agent writes it
- CLIno code at all
- MCPexpose ADE docs as an agent tool
- REST APIany language
- Pythonlandingai-ade
- TypeScriptlandingai-ade
Documents into data
Accurate
The best accuracy on the difficult documents other tools get wrong, such as messy scans, complicated tables, checkboxes and handwriting.
Auditable
Every answer cites its sources. Values come back with an audit trail (page, bounding box, character range) so a human can review them.
Agentic
Applies multi-step reasoning, and plans before it acts. Handles documents it has never seen before and adapts to variations.
API-first
Composable APIs that drop into any tech stack and can be called from anywhere. Easy to build on and embed in your pipelines and products.
Affordable
Cost-competitive rates with complete price transparency. Spend controls before you run, and every job reports its exact cost.
Enterprise-grade
Built for production and scale from day one. Fully observable and monitored, running securely in our cloud or yours.
Built for high-volume, high-throughput production
- Zero data retention
- Priority rate limits
- Enhanced support
- VPC and on-prem deployment
Available on Team and Enterprise plans.